The Workstation Blog
LLM
Posts tagged LLM.
Gemini 4 Argon: What It Means for Your Team, and Where to Use It First
Gemini 4 Argon is built to work for hours on one measurable problem. Here is what shipped, the real costs, and how to pilot it safely on your own backlog.
 Balinder WaliaRead
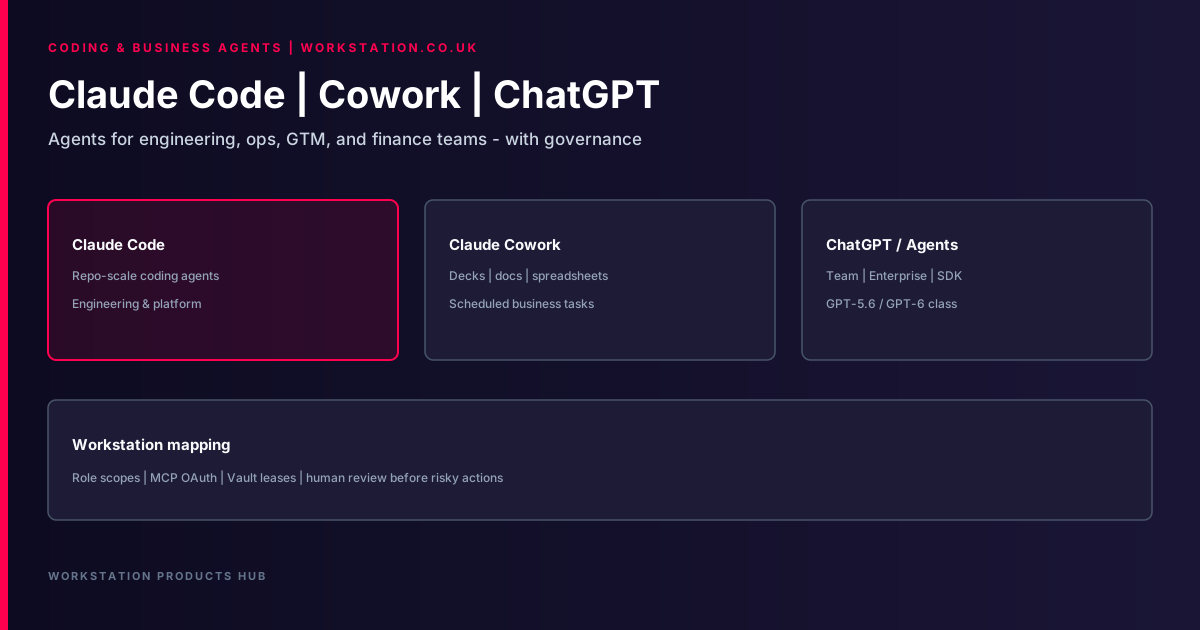
Claude Code, Claude Cowork & ChatGPT for Business Teams
Which teams should use Claude Code, Claude Cowork, or ChatGPT/OpenAI Agents — and the controls Workstation recommends before production.
Balinder WaliaRead 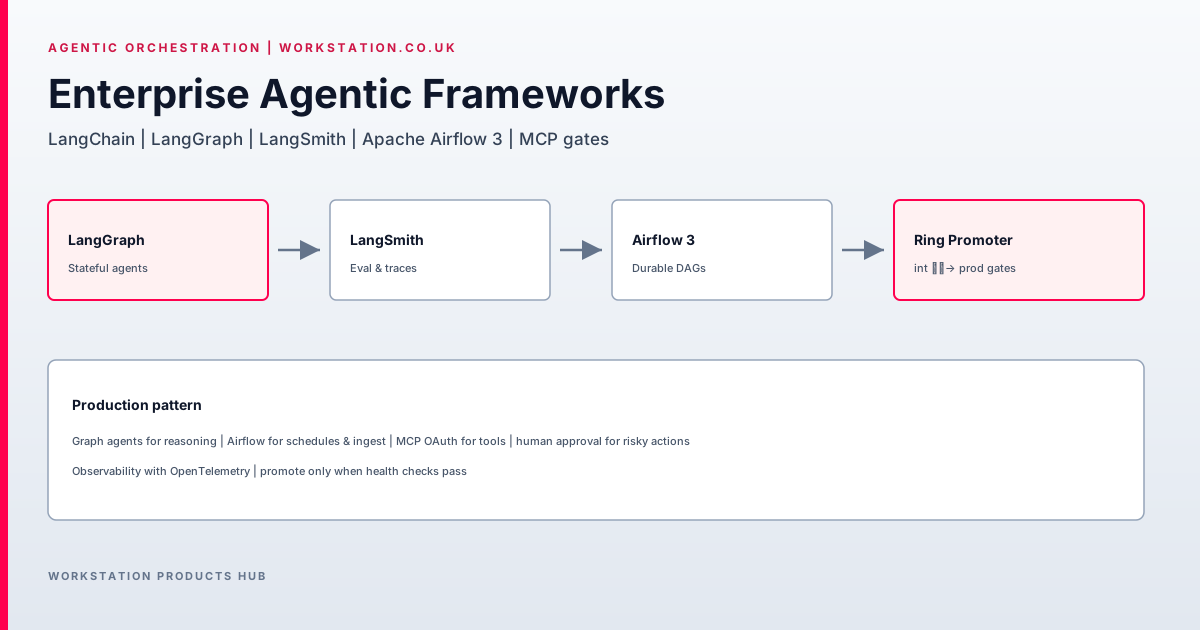
Enterprise Agentic Frameworks: LangChain, LangGraph & Airflow 3
Operational guide to LangGraph agents, LangSmith evals, and Apache Airflow 3 schedules — with Workstation promotion and edge patterns.
Balinder WaliaRead 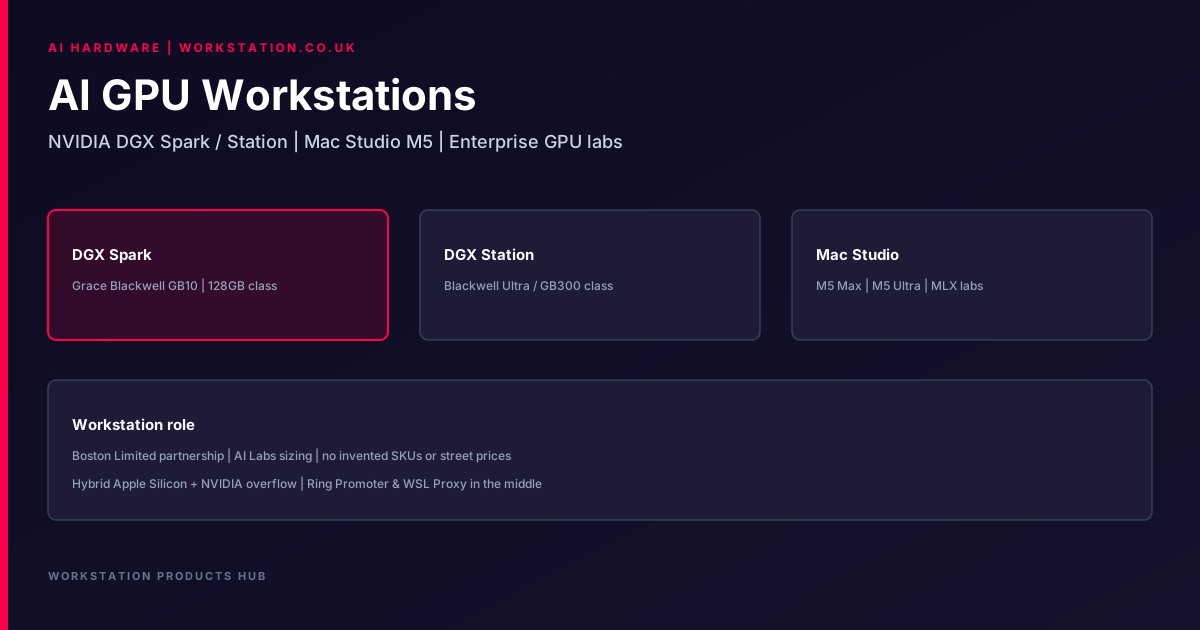
AI GPU Workstations: NVIDIA DGX Spark/Station & Mac Studio M5
How Workstation maps NVIDIA DGX Spark, DGX Station, and Mac Studio M5 into AI Labs and SME packages — factual positioning, no invented prices.
Balinder WaliaRead 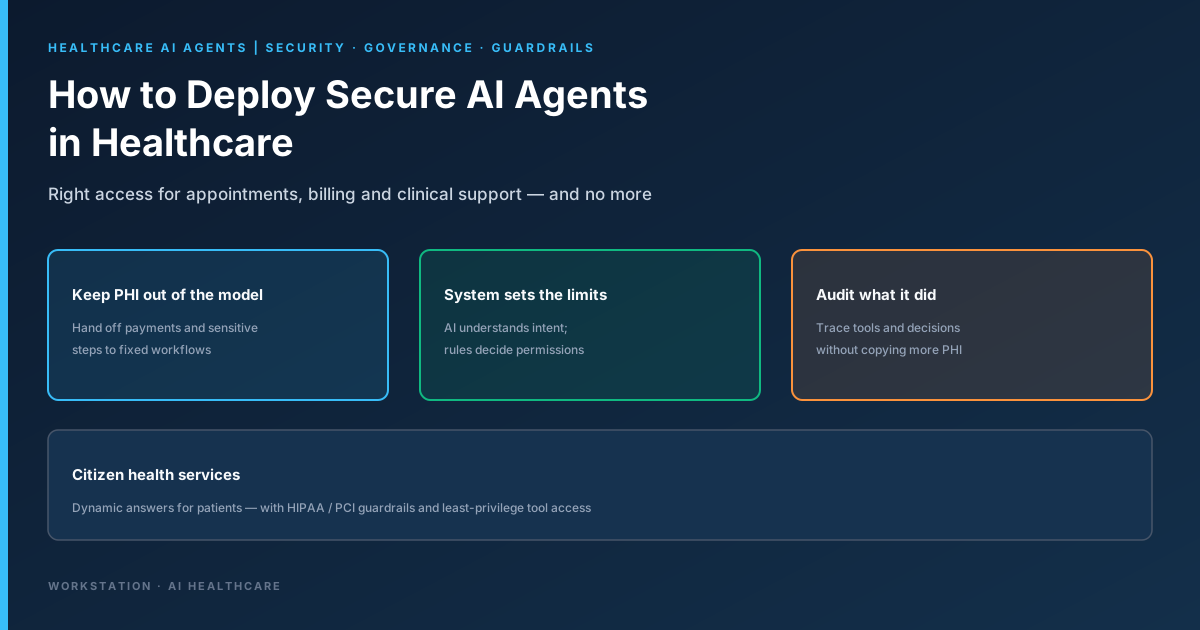
How to Deploy Secure AI Agents in Healthcare
AI agents can book appointments, take payments and support clinical work. Here is how healthcare teams can give them the right access, and no more.
Balinder WaliaRead 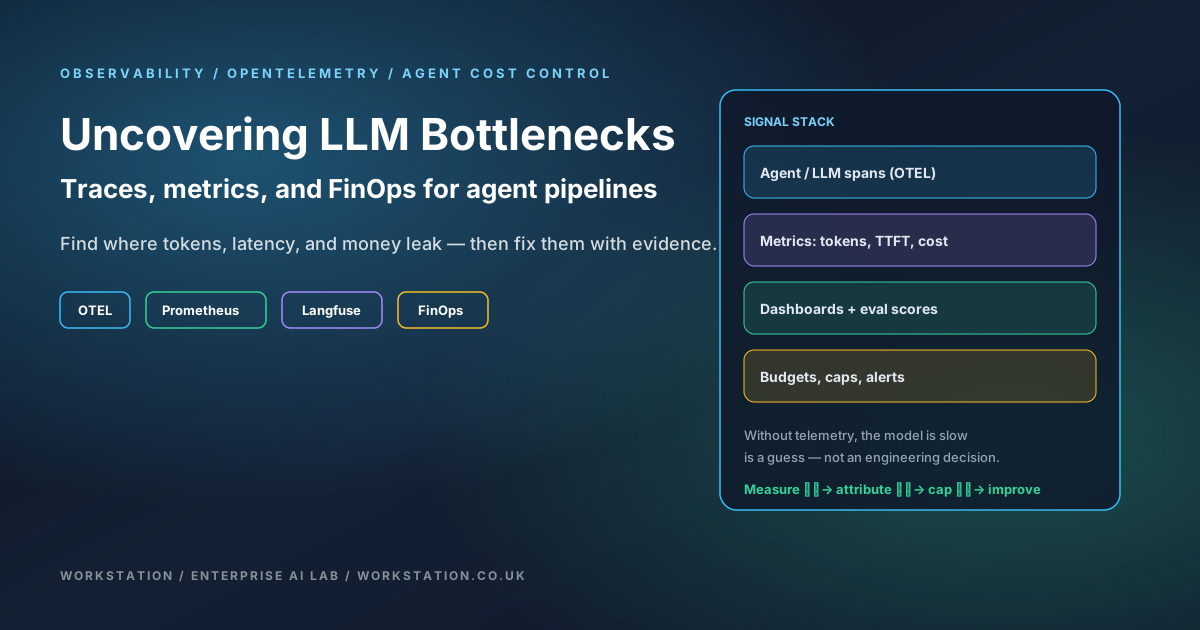
Uncovering LLM Bottlenecks: Observability, OTEL & Cost Control
Workstation on uncovering LLM agent bottlenecks with observability: OpenTelemetry, Prometheus/Grafana/Thanos, Langfuse — with clear pros/cons, cost levers, and usage metrics that protect margins.
Balinder WaliaRead 
Turbocharging LLMs
Workstation on turbocharging LLMs: PagedAttention paging for KV cache, vLLM serving, Self-Debugging for agents, PowerInfer token rates, and EG-MLA memory cuts — with production trade-offs.
Balinder WaliaRead 
KubePilot: CoPilot, Pilot & AutoPilot for Faster Kubernetes Incidents
KubePilot helps SRE, DevOps, and platform teams move from noisy cluster signals to a safe fix — CoPilot, Pilot, and AutoPilot. Open source at kubepilot.org.
Balinder WaliaRead